Table of Contents
In scale up strategy resources are enhanced to a single node whereas in scale out more nodes are added to distribute the AI workloads.
When systems are nearing their optimum capacity then infrastructure administrators need to make decisions on expansion or new provisioning based on the application or website requirements for scaling. The artificial intelligence enabled systems heavily rely on computing power. As the AI model size grows the computation demand also grows multi-fold. AI workloads are powered by GPUs, NPUs and TPUs which are a combination of AI servers and large scale computing clusters used for AI inference and training.
Decision to scale up and scale out that is vertical scaling or horizontal scaling depends on organization requirements they may adapt one of the strategies or a mix of both.
In today’s article we will cover in detail about scale up and scale out strategies implemented for AI infrastructure, key benefits, differences and use cases.
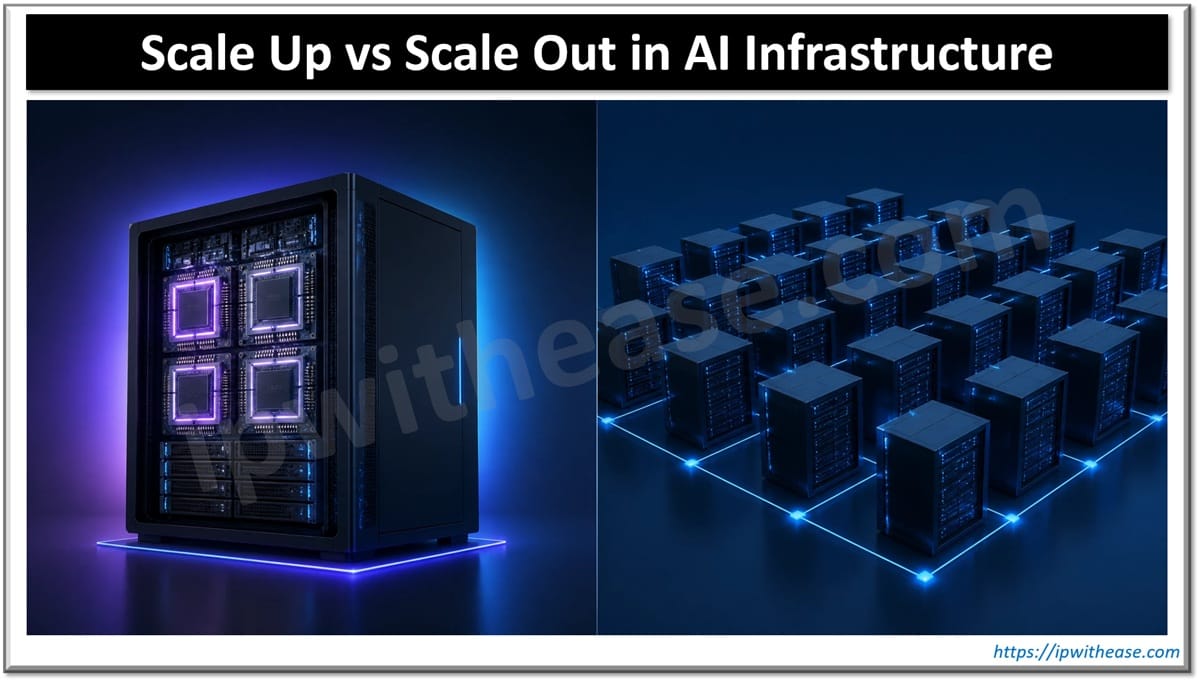
What is Scale Up in AI Infrastructure
Scale up architecture was first introduced by IBM in the 1960s and 1970s. Scale up as the name suggests is improvising the existing resource computing capability by adding more compute resources to a single node. The hardware resources such as GPUs, TPUs and NPUs, memory, storage is added to individual nodes such as upgrading CPU from 4 core to 64 core.
In AI terms this usually means adding more GPUs to one system, moving to accelerators with larger high-bandwidth memory (HBM), and linking those GPUs with a very fast, low-latency interconnect such as NVIDIA NVLink and NVSwitch.
The goal is to make many GPUs behave like one large accelerator. GPUs inside a scale-up domain share memory access at speeds far beyond what any network can deliver. Rack-scale systems like NVIDIA’s GB200 NVL72 push this idea further by stretching the scale-up domain from a single server to an entire rack.
Key Points
- Best suited for tensor parallelism, where a single model layer is split across GPUs and they must exchange data constantly.
- Delivers the lowest latency for GPU-to-GPU communication, which matters for large model inference and tightly coupled training.
- Limited by physics: power, cooling, board space and copper cable reach cap how large one domain can grow.
- Concentrates risk. A failure in the node or its interconnect fabric can take down the whole job running on it.
- Expensive per unit, since it relies on specialized, often proprietary hardware.
What is Scale Out in AI Infrastructure
Scale out architecture was pioneered by Google and this concept emerged around the year 2000. Scale out as the name suggests means horizontal expansion by adding more nodes and using load balancers for workload distribution. This is commonly used in cloud computing where hundreds of servers together are a distributed cluster.
In AI clusters this is the “back-end” network built on InfiniBand or high-performance Ethernet (RoCE), often designed as rail-optimized, non-blocking fabrics so that thousands of GPUs can communicate during training.
This is how frontier models are trained. No single node or rack holds enough compute, so work is spread across hundreds or thousands of servers. Industry efforts such as the Ultra Ethernet Consortium exist precisely because scale-out networking has become a bottleneck worth standardizing.
Key Points
- Best suited for data parallelism and pipeline parallelism, where communication between nodes is less frequent than inside a node.
- Grows almost without a ceiling. Capacity is added node by node as demand grows.
- More resilient. Jobs can checkpoint and restart, and a failed node can be swapped out without rebuilding the cluster.
- Network becomes the critical path. Congestion, packet loss and tail latency directly slow down collective operations like all-reduce.
- Operationally heavier, with many nodes, optics, switches and firmware versions to manage.
How They Work Together
Modern AI clusters use both, in layers. GPUs within a node or rack form a scale-up domain connected by NVLink-class links, handling the most chatty traffic. Those domains are then connected through a scale-out fabric that carries gradient synchronization and data movement across the cluster. A well-designed system maps each type of parallelism to the network tier that suits it: tensor parallelism stays inside the scale-up domain, while data and pipeline parallelism cross the scale-out fabric.
The practical question for an architect is rarely “which one?” It’s how large the scale-up domain should be, and how well the scale-out network can keep those domains fed.
Comparison: Scale Up vs Scale Out in AI Infrastructure
| Feature | Scale Up (Vertical) | Scale Out (Horizontal) |
|---|---|---|
| Approach | More GPUs, memory and bandwidth in one node or rack | More nodes connected over a network fabric |
| Interconnect | NVLink, NVSwitch, emerging UALink | InfiniBand, RoCE Ethernet, Ultra Ethernet |
| Latency | Very low, near memory-level speeds | Higher, dependent on fabric design and congestion |
| Best-fit parallelism | Tensor parallelism | Data and pipeline parallelism |
| Scalability limit | Capped by power, cooling and cable reach | Practically unlimited, bounded by network design |
| Fault tolerance | Single domain is a point of failure | Higher, failed nodes can be isolated and replaced |
| Cost model | High upfront, specialized hardware | Incremental, grows with node count |
| Typical use | Large model inference, tightly coupled training | Large-scale distributed training, multi-tenant clusters |
| Operational complexity | Lower, fewer components | Higher, many nodes, optics and switches |
| Main bottleneck | Physical limits of the domain | Network bandwidth, congestion and tail latency |
Download the comparison table: scale up vs scale out in ai infrastructure
Final Words
Scale up and scale out are not competing strategies in AI infrastructure. They are two layers of the same design. Scale up gives you raw speed where GPUs need to talk constantly, while scale out gives you the reach to train and serve models that no single rack could handle on its own.
The real engineering challenge sits at the boundary between them. Make the scale-up domain too small and your network gets flooded with traffic it was never meant to carry. Underinvest in the scale-out fabric and expensive GPUs sit idle, waiting on data. Getting the balance right depends on the models you run, the parallelism strategy you choose, and how much growth you expect.
ABOUT THE AUTHOR
You can learn more about her on her linkedin profile – Rashmi Bhardwaj